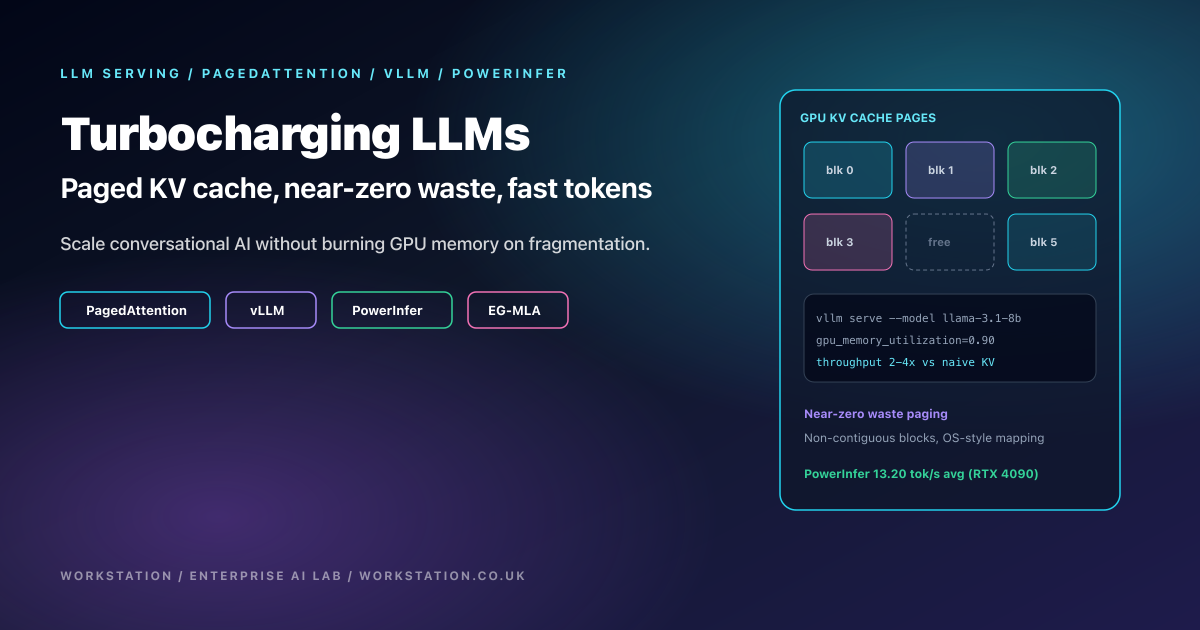
Turbocharging LLMs
TenthMatrix on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
Topic
Posts tagged Machine Learning
TenthMatrix on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
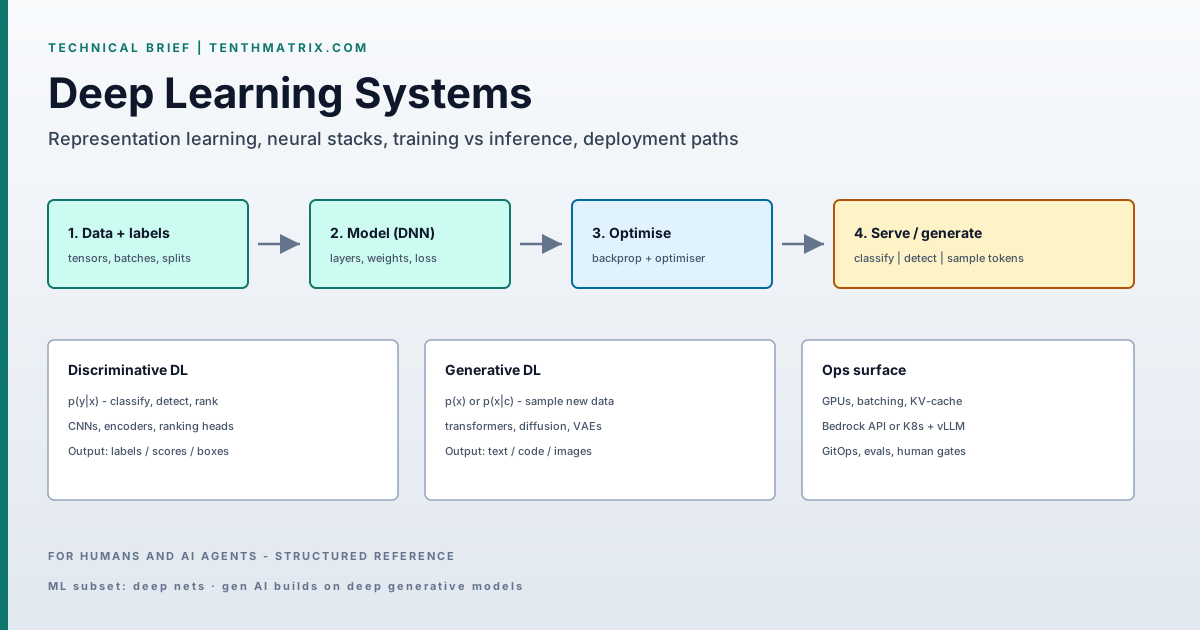
Technical TenthMatrix brief on deep learning: gradient-trained deep nets, discriminative vs generative models, task metrics, and Bedrock vs Kubernetes serving.
What are Large Language Models and how do they work? A clear, non-technical explainer for managers and engineers — tokens, embeddings, transformers, training and inference — plus production Kubernetes YAML to deploy your own LLM with Ollama and vLLM.